Databricks, for data engineering and AI at real scale.
Databricks is where our biggest data engineering and machine learning workloads run — one platform for the pipeline, the warehouse, and the model training that sits on top, instead of stitching several specialist tools together.


Where Databricks earns its place in the stack.
Large-scale data pipelines
Apache Spark under the hood means transformations that would choke a single machine run comfortably distributed across a cluster.
Lakehouse architecture
One copy of the data serves BI and machine learning both — no separate warehouse and data lake quietly drifting out of sync with each other.
ML and AI model training at scale
From experimentation to production training, Databricks handles the compute without a separate platform for "the AI part."
Collaborative notebooks for data teams
Engineers, analysts and data scientists work from the same environment, on the same data, without exporting to a dozen local copies.
One platform for data engineering and AI.
Databricks earns its place on the biggest, most demanding data workloads we build — where the volume, the governance requirements, or the need to train models on the same data genuinely justifies a dedicated platform.
It's not the right tool for every job. For a smaller product, PostgreSQL usually does the job with far less operational overhead. Databricks is what we reach for once the scale or the ML requirements make that trade-off worth it.
One platform, not two
Data engineering and machine learning happen in the same place, on the same governed data — not a pipeline team and an ML team working from different copies.
Built on open standards
Delta Lake and Spark underneath mean the data isn't locked into a proprietary format — a real consideration when a client wants to avoid vendor lock-in.
Scales from a laptop-sized job to genuinely huge
The same code that runs a quick exploration scales up to a production pipeline processing far more data, without a rewrite.
Real governance and lineage
Unity Catalog gives a clear picture of where data came from and who can access it — not an afterthought bolted on once something goes wrong.
Not sure Databricks is the right fit? Ask the engineer who'd build it.
Book a 30-minute working session with a senior engineer — a real conversation about your data, not a sales call.
Where the platform did the heavy lifting.
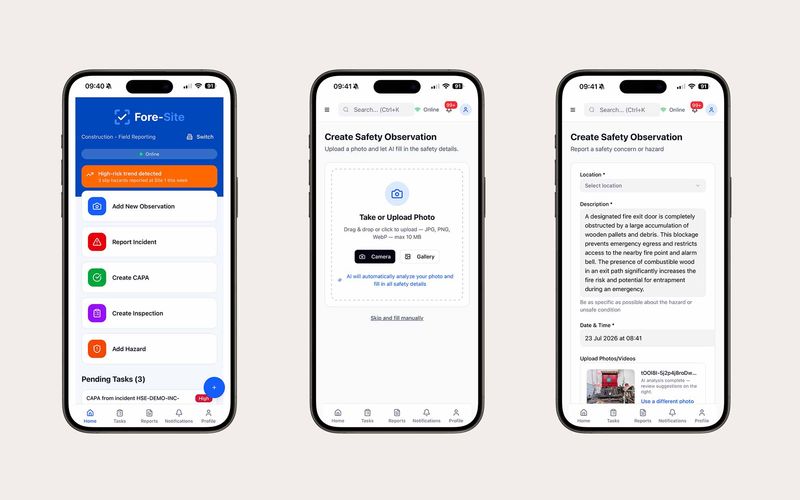
AI HSE reporting, from a single photo.
Our own product: an AI-powered progressive web app that turns a single photo into a complete observation, incident or hazard report — with a desktop command centre for tracking, investigation and approvals. Works offline and syncs on reconnect.
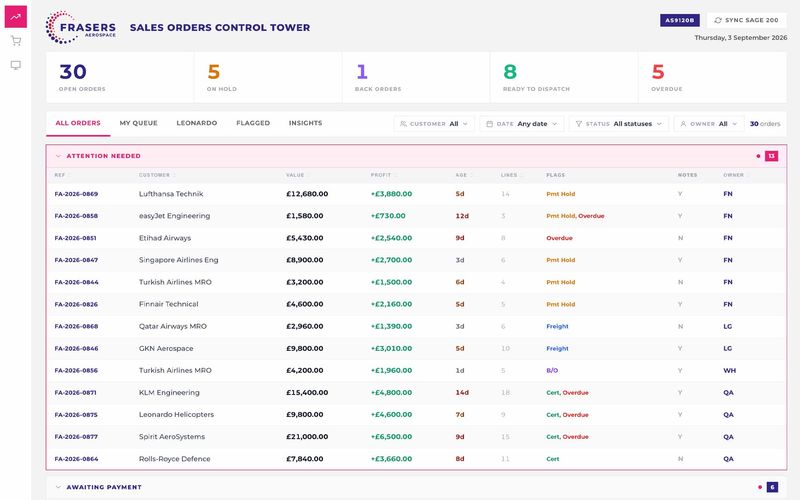
Frasers Aerospace — Operations Control Tower
An operations dashboard for an AS9120B aerospace supplier, built in Microsoft Lists and Power BI — orders from Sage 200 and WooCommerce in one place, the spreadsheets they used to be raised in retired, the exceptions blocking them surfaced first, and a TV wallboard for the warehouse floor.
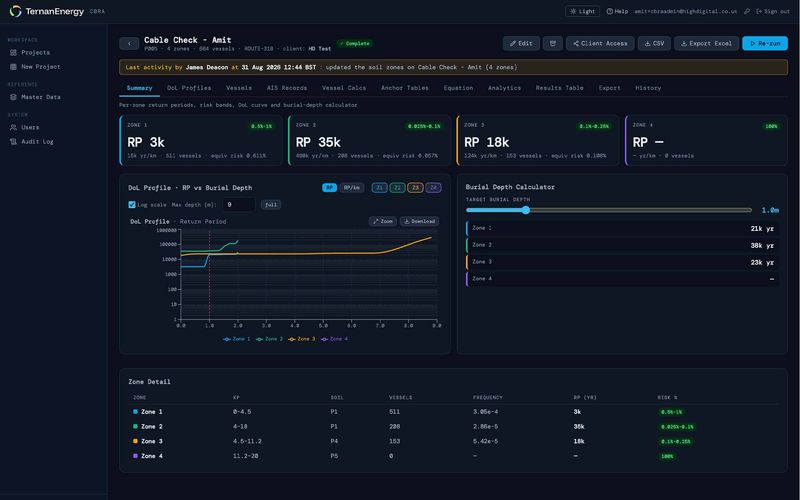
A 12-tab spreadsheet, rebuilt as a risk platform
Offshore cable burial risk assessment taken out of a straining Excel workbook and rebuilt as a Python engine and React application on Microsoft Azure — a hundred thousand rows of AIS vessel data, Carbon Trust anchor-strike methodology, and depth-of-lowering curves for every soil zone on a route.
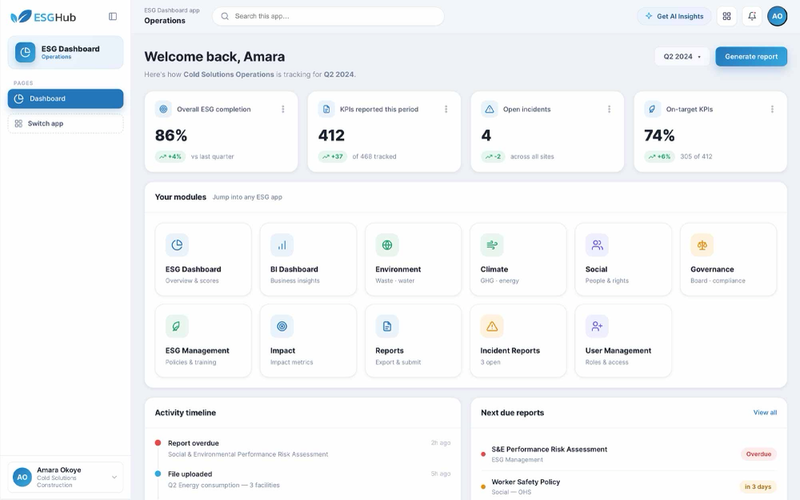
Real-time carbon & compliance reporting for cold chain.
A data management platform built to manage ESG data and deliver ESG insights, analytics and reports to the business and its stakeholders.
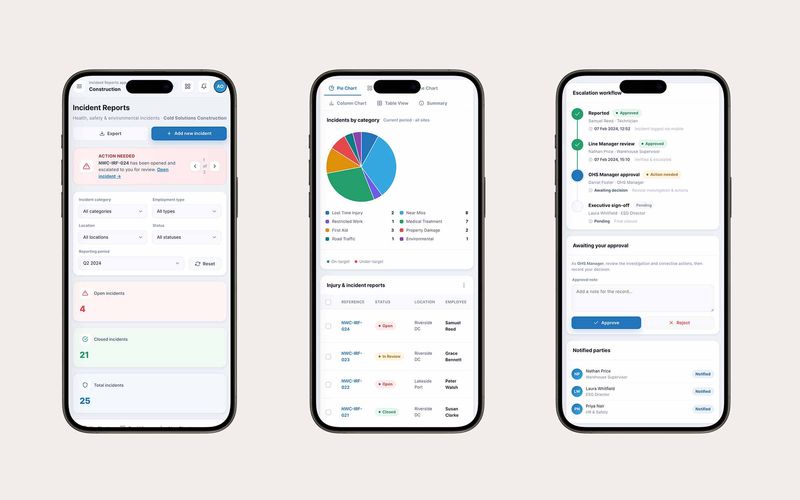
Time-critical incident reporting, built for the field.
A realtime incident reporting application built to collect, escalate and report on incident data across the cold chain and construction business.
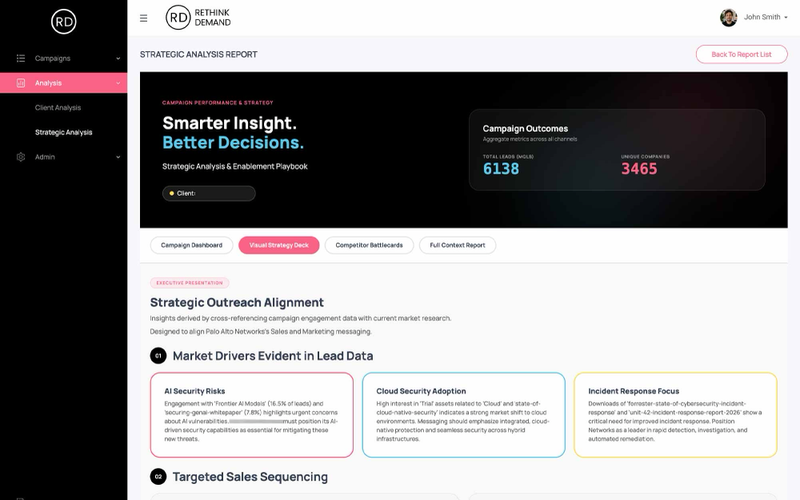
A single source of truth for prospect intelligence.
A centralised platform to manage the acquisition, cleansing, matching and enrichment of prospect data at scale — replacing fragmented sources and manual scoring with one unified system.
What a Databricks build usually includes.
More on Databricks, and how we use it.
High Digital Earns OpenAI ChatGPT & Codex Solutions Practitioner Recognition
High Digital has earned both ChatGPT Solutions Practitioner and Codex Solutions Practitioner recognition from the OpenAI Partner Network.
Read more
n8n Alternatives in 2026: How to Choose a Workflow Automation Platform (and When to Build Your Own)
Week 1 of the High Digital Workflow Automation Series. We compare the leading n8n alternatives by how they bill, where they run and who they suit, and when building your own makes more sense.
Read more
Proposal App AI-Driven Scoping & Estimation
Week 6 of the High Digital AI Initiatives Series. We’ve saved one of our biggest commercial bottlenecks for last: generating enterprise project proposals.
Read moreThe stack we ship on.
Pragmatic, mostly boring, and chosen because it works in production — not because it's on the front page of Hacker News.
Have an outcome in mind?
We'll help you
ship it.
- You're building a data product and need a team that can deliver.
- You want to get AI-ready — pragmatically, not theoretically.
- Your reporting is a mess and you need a real platform underneath it.